E-Paper


The big Microsoft outage, AI and a comprehension debt
AI agents are writing millions of lines of code, raising concerns that engineers cannot review the output fast enough or fully understand the systems they build

 Prefer HTon Google


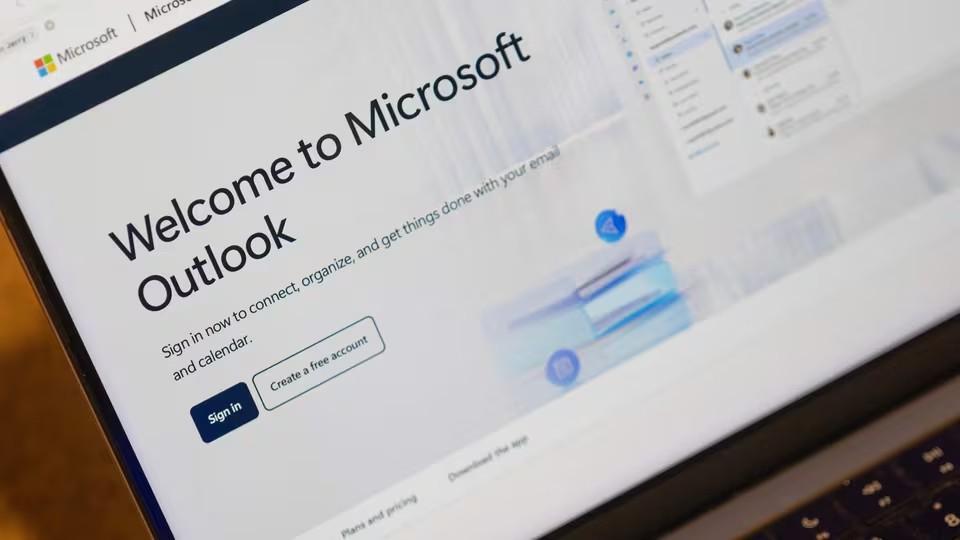
A global outage affecting Microsoft’s enterprise and consumer services stretched into several hours on Friday. The company described the impact on apps including Outlook, Teams, OneDrive and Office on the web as a “service degradation”, while engineers tried implementing fix after fix. Fourteen hours later, Microsoft finally said it had started noticing “positive results for service stability and increased capacity”, but the disruption was far from over.
"We’re seeing encouraging recovery progress, with service availability and email delivery performance improving across a growing portion of affected infrastructure. We know our customers rely on our services to get important work done every day, and regret the impact these outages had on those who depend on us. Our teams are reviewing what happened and how we can prevent similar issues going forward,” says Charles Lamanna, EVP, Copilot, Agents and Platform at Microsoft, in a statement shared with HT.
The cause officially cited was that something in the system caused otherwise perfectly fine servers to start failing automated health checks, which meant the load was shifted to other servers. They also began to struggle as a result, leading to instability. While Microsoft hasn’t yet attributed the outage to any code written by artificial intelligence (AI), it comes against the backdrop of the tech giant’s aggressive AI deployment.
Two pressing questions have emerged: are companies relying too much on AI to write code, and are they quietly losing the institutional understanding needed to fix their own systems in times of crisis?
Deep Dive

Govind Rammurthy, CEO and managing director of eScan, an enterprise security company, says this raises legitimate structural questions, which must nevertheless be contemplated despite Microsoft not attributing the failed automated health checks that triggered the cascading effect to AI-generated code. “Speed and scale are not the problem; irreversibility is, as has been seen in this specific case of outage,” he says.
In April last year, CEO Satya Nadella claimed that as much as 30% of the code within the company was being written by AI already, and that share was increasing steadily. In June this year, Microsoft wound down and cancelled internal direct licences for Anthropic’s Claude Code for internal use, due to massive token consumption and compute costs.
Microsoft nudged engineers to use its own GitHub Copilot CLI, an autonomous, terminal-native AI coding agent. Compared with Claude, it is a bit more cost-effective. It isn’t clear what level of human oversight remained for the code being written by AI.
Microsoft reiterated throughout the hours of the outage that no malicious activity or cyberattacks were behind it. Nevertheless, the impact has been global and widespread — affecting schools, government services, banks and even airline communication and support services in some countries.
The comprehension debt
As AI agents write and commit millions of lines of code, with enterprises believing the process is faster, more accurate and cost-effective compared with human coding, that pace is often faster than humans can review the code, if they review it at all.
Even without a smoking gun having been discovered in the Microsoft outage, enterprises and hyperscalers are adopting the concept of ‘comprehension debt’, where no single human engineer fully understands the system architecture when a novel failure needs to be resolved. Engineers may have to read through thousands of lines of code to understand what went wrong.
“Since AI-assisted development and agentic coding have become commonplace, organisations find themselves in a stage of producing code at an unprecedented rate. The rate at which code is created outpaces any kind of testing or validation techniques available today,” says Padma Reddy Sama, CTO and co-founder of BharathCloud, an enterprise cloud platform.
Sama insists that when systems and components develop and evolve rapidly, engineering teams lose their ability to understand the interactions between those components and potential risks.
“In today’s daily software development routine, AI agents write, save and commit code at a very rapid pace. And, when AI agents commit code faster than human engineers can meaningfully review it, organisations accumulate what you correctly call comprehension debt: systems that work until an edge case hits, at which point no single engineer holds a complete enough mental model to diagnose quickly,” Rammurthy explains.
“Comprehension debt builds when understanding of a system lags behind how quickly it changes. Organisations adopting AI at enterprise scale generally find the answer lies in better process design. The priority is to structure AI workflows around clear ownership: someone accountable for each agent-generated change, architectural choices on record, and closer review where the potential impact is greater,” says Shailesh Dhuri, CEO and co-founder of Decimal Point Analytics, a research firm.
An illustration of why comprehension debt is a problem is provided by instances of false positives that Microsoft’s 365 Status account on X shared in the early hours of the outage. “Our mitigative actions have successfully restored service health and functionality. Customer impact is now fully resolved,” the account posted, with a sense of achievement. But that was not the case, as users around the world discovered in the hours that followed.
Taran Srivastava, co-founder of ML.ai, an AI infrastructure company, says, “Writing code used to be the slow part of software. Now the slow part is understanding it, and when agents commit changes faster than people can review them, the gap between what’s been shipped and what anyone can explain keeps widening.”
By estimates, Microsoft has let go of around 8,000 employees in the past year, though it is difficult to get an exact number of engineering staff asked to leave. In October, Microsoft also rolled out a voluntary exit programme for more than 60,000 eligible employees across many countries — and they have until December 9 to decide.
Speed, velocity and a mess AI cannot solve
Microsoft attributed the outage to several servers unexpectedly becoming unavailable after failing automated health checks (which caused them to go into a non-active state), placing elevated strain on the remaining infrastructure worldwide. Those servers, in turn, began to fail, setting off a chain reaction.
The attempted fixes that Microsoft officially mentioned included restarting servers that had malfunctioned and reverting them to earlier configurations which had seemingly worked earlier.
“Microsoft’s prolonged recovery confirms that AI infrastructure tooling is excellent at detecting known failure patterns and executing pre-scripted remediation, but it is poor at novel failure modes, especially cascading ones where the system behaves unexpectedly under load. Self-healing works for anticipated, or in other words, predicted failures,” Rammurthy explains.
The biggest impact was on email and communications globally, across businesses, governments and consumers, with Outlook and Teams among the affected services.
He further adds that there are certain failures or instances which require human judgement that no current AI system can reliably replace, and calls on controls to limit the potential impact of AI deployment. “The structural guard-rail is straightforward: deployment velocity must be governed by rollback capability. Any configuration change that cannot be fully reversed within minutes should not reach production at all,” he says.
Restarting a server, unlike restarting a computer which most of us are familiar with, can take as long as 30 minutes for all processes to boot up and go online, depending on the hardware and workload. After an unexpected crash or hard reboot, the server may additionally run a disk check process, which can take a while on large drives.
“For an infrastructure to be termed as self-healing, it is not enough to just recognise the problem with a server and to restart it. The system needs to know what has caused the problem, whether it can be solved by restarting the server, the effect that restarting it would have on other connected services, and whether it would sustain under load,” explains Sama.
There are no guarantees that an issue which caused the server to shut down or become unresponsive in the first place will be fixed by a restart.
“Novel, cascading failures are harder, because they need context across systems and judgment that agents do not yet provide reliably. That is why enterprises moving from AI experimentation to production tend to focus on governance as much as capability,” says Dhuri, noting that, irrespective of industry, the principle is the same: automation should add speed while human oversight stays proportionate to the risk.
“It’s a useful reality check on the claim that AI will not only write and ship software but also repair its own failures,” says Srivastava.
“The risk isn’t that AI writes bad code. It’s that scale and velocity outpace understanding, and that gap only becomes visible under failure conditions, precisely when clarity matters most. This outage, whatever its cause, illustrates that gap perfectly,” says Rammurthy.
There are concerns, particularly among Outlook users, about service restoration and whether there has been any data loss.